Today
Front-end, in one read.
The latest from the sources worth following, newest first.
DEV CommunityThe Giantsread at source
10 estudios nuevos sobre el arriendo en Bogotá: localidades, estratos, amoblados, mascotas, amenidades y barrios (octubre 2026)
Publicamos diez estudios nuevos con datos abiertos (CC BY 4.0) sobre el mercado de arriendo de apartamentos en Bogotá, elaborados por AptologÃa con avisos de arriendo de octubre de 2026. Cada estudio incluye un CSV, gráficas y metodologÃa, y está archivado en Zenodo con DOI y en OSF. Arriendo en Bogotá por localidad: precio mediano, por m² y de 2 habitaciones (octubre 2026) El arriendo mediano de un apartamento en Bogotá va de COP 1.000.000 en Usme a COP 4.495.000 en Chapinero: 4,5 veces más. Un 2 habitaciones cuesta en la mediana COP 1.443.500 en Kennedy, COP 1.850.000 en Suba y COP 4.610.000 en Chapinero. Estudio completo: https://www.aptologia.com/estudios/arriendo-por-localidad-bogota Datos (Zenodo): https://doi.org/10.5281/zenodo.23343314 OSF: https://osf.io/uwx6z/ Apartaestudio o apartamento de 1 habitación en Bogotá: precio, área y m² por estrato (2026) En Bogotá, un apartamento de 1 habitación cuesta en la mediana COP 2.400.000 al mes y un apartaestudio COP 1.950.000: COP 450.000 más. El de 1 habitación tiene 40 m² frente a 31 m² del apartaestudio, y por m² el apartaestudio sale a COP 63.462 contra COP 62.500. Estudio completo: https://www.aptologia.com/estudios/apartaestudio-vs-apartamento-1-habitacion-bogota Datos (Zenodo): https://doi.org/10.5281/zenodo.23343349 OSF: https://osf.io/zy6a7/ ¿Cuánto más cuesta un apartamento amoblado en arriendo en Bogotá? (octubre 2026) En Bogotá, un apartamento en arriendo que está amoblado cuesta en promedio 22,9 % más por metro cuadrado que uno comparable del mismo estrato y número de habitaciones. Lo menciona el 13,7 % de los avisos con descripción; el canon mediano de los que sà es COP 4.100.000 frente a COP 2.200.000 de los que no. Estudio completo: https://www.aptologia.com/estudios/arriendo-amoblado-bogota Datos (Zenodo): https://doi.org/10.5281/zenodo.23343380 OSF: https://osf.io/37vh4/ Apartamentos que aceptan mascotas en Bogotá: cuántos hay y cuánto más cuestan (2026) En Bogotá, un apartamento en arriendo que acepta mascotas cuesta en promedio 7,0 % más por metro cuadrado que uno comparable del mismo estrato y número de habitaciones. Lo menciona el 3,6 % de los avisos con descripción; el canon mediano de los que sà es COP 2.100.000 frente a COP 2.500.000 de los que no. Estudio completo: https://www.aptologia.com/estudios/arriendo-con-mascotas-bogota Datos (Zenodo): https://doi.org/10.5281/zenodo.23344583 OSF: https://osf.io/3urxs/ ¿Cuánto valen el ascensor, el gimnasio, la piscina y otras amenidades en un arriendo en Bogotá? (2026) En Bogotá, la amenidad que más sube el arriendo es balcón: 11,0 % más por m² que un apartamento comparable del mismo estrato y habitaciones. Le siguen piscina (10,3 %) y gimnasio (9,3 %). En cambio, parqueadero de visitantes, chimenea, ascensor no suben el precio por m² (entre -2,3 % y -1,4 %). Estudio completo: https://www.aptologia.com/estudios/cuanto-valen-las-amenidades-arriendo-bogota Datos (Zenodo): https://doi.org/10.5281/zenodo.23344623 OSF: https://osf.io/s8uea/ Piso alto o piso bajo: cuánto cambia el arriendo según el piso en Bogotá (2026) En Bogotá, un apartamento en piso 11 o más arrienda 31,9 % más por metro cuadrado que uno comparable en piso 1, del mismo estrato y número de habitaciones. Los pisos 2-3 cambian 11,1 % y los pisos 7-10 26,8 %. Estudio completo: https://www.aptologia.com/estudios/piso-alto-vs-piso-bajo-arriendo-bogota Datos (Zenodo): https://doi.org/10.5281/zenodo.23344634 OSF: https://osf.io/jbdyt/ Edificio nuevo o viejo: cuánto cambia el arriendo según la antigüedad en Bogotá (2026) En Bogotá, un apartamento en un edificio de 0 a 5 años arrienda 26,7 % más por metro cuadrado que uno comparable en un edificio de más de 20 años. Pero los edificios viejos tienen apartamentos más grandes: 104 m² en la mediana frente a 42 m² en los nuevos. Estudio completo: https://www.aptologia.com/estudios/antiguedad-del-edificio-arriendo-bogota Datos (Zenodo): https://doi.org/10.5281/zenodo.23344643 OSF: https://osf.io/3ghej/ Cuánto cuesta arrendar en Bogotá según estrato y número de habitaciones: tabla completa (2026) En Bogotá, un apartamento de 2 habitaciones cuesta en la mediana COP 1.500.000 en estrato 3, COP 2.500.000 en estrato 4 y COP 7.500.000 en estrato 6. Pasar de 2 a 3 habitaciones en estrato 4 sube el canon de COP 2.500.000 a COP 3.300.000. Estudio completo: https://www.aptologia.com/estudios/arriendo-por-estrato-y-habitaciones-bogota Datos (Zenodo): https://doi.org/10.5281/zenodo.23344656 OSF: https://osf.io/w9hfd/ Barrios para estudiantes en Bogotá: apartaestudios y 1 habitación cerca de las universidades (2026) Cerca de las universidades de Bogotá, el apartaestudio o apartamento de 1 habitación más barato está en Siete De Agosto (Barrios Unidos), con un canon mediano de COP 1.500.000. Por localidad, la mediana va de COP 1.500.000 en Los Mártires a COP 2.400.000 en Chapinero. Estudio completo: https://www.aptologia.com/estudios/barrios-para-estudiantes-bogota Datos (Zenodo): https://doi.org/10.5281/zenodo.23344664 OSF: https://osf.io/ecdga/ Barrios para familias en Bogotá: 3 habitaciones con parqueadero, precio y metros por millón (2026) En Bogotá, un apartamento familiar (3 habitaciones o más, parqueadero y 70 m² o más) cuesta en la mediana COP 10.000.000 al mes: COP 2.800.000 en estrato 3 y COP 3.661.000 en estrato 4. Por estrato, los barrios que más metros dan por cada millón son Cedritos (estrato 4, 28,4 m²), La Calleja (estrato 5, 21,9 m²), Santa Barbara Occidental (estrato 6, 23,1 m²). Estudio completo: https://www.aptologia.com/estudios/barrios-para-familias-bogota Datos (Zenodo): https://doi.org/10.5281/zenodo.23344672 OSF: https://osf.io/adpgf/ Autor: Daniel Mauricio Pinzón Pineda ( ORCID 0009-0007-5142-366X ) · Licencia de los datos: CC BY 4.0.
DEV CommunityThe Giantsread at source
Optimistic vs. Pessimistic Locking in PostgreSQL & Node.js: Preventing Inventory Overselling
You launch a sale. There are 10 units of a hot item in stock. Fifteen people click "Buy" within the same second. When the dust settles, your database says: stock = -2 orders confirmed = 12 Two customers are getting an apology email. Support is unhappy, and finance wants to know how the stock count went negative. This is the lost update problem, and it's one of the classic concurrency bugs in backend code. It doesn't show up in development (one user, one request at a time), it passes unit tests, and then it appears the first time real concurrent traffic hits the same row. In this post we'll reproduce the bug, then fix it three ways with PostgreSQL and Node.js: Atomic conditional updates (often all you need) Pessimistic locking ( SELECT ... FOR UPDATE ) Optimistic locking (version checks with retries) We'll compare them honestly, because the right choice depends on your contention level. The bug: read, check, write Here's the code almost everyone writes first: // ❌ Race condition async function purchase ( productId : number , qty : number ) { const { rows } = await pool . query ( ' SELECT stock FROM products WHERE id = $1 ' , [ productId ]); const stock = rows [ 0 ]. stock ; if ( stock qty ) throw new OutOfStockError (); await pool . query ( ' UPDATE products SET stock = $1 WHERE id = $2 ' , [ stock - qty , productId ]); await pool . query ( ' INSERT INTO orders (product_id, qty) VALUES ($1, $2) ' , [ productId , qty ]); } Now two requests run at the same time with stock = 1 : Request A Request B SELECT stock → 1 SELECT stock → 1 check 1 >= 1 ✓ check 1 >= 1 ✓ UPDATE stock = 0 UPDATE stock = 0 ← overwrites A; both think they got the last unit INSERT order INSERT order ← two orders, one unit Both requests read the same value, both pass the check, and the second write silently clobbers the first. The gap between the read and the write is the race window. Every fix below is a different way of closing it. Prove it before you fix it Make this a test you keep forever. If you can't reproduce the bug, you can't trust the fix: // oversell.test.ts import { it , expect , beforeEach } from ' vitest ' ; beforeEach ( async () => { await pool . query ( ' TRUNCATE orders RESTART IDENTITY ' ); await pool . query ( " UPDATE products SET stock = 10 WHERE id = 1 " ); }); it ( ' never sells more than the available stock ' , async () => { // 50 buyers fight over 10 units const results = await Promise . allSettled ( Array . from ({ length : 50 }, () => purchase ( 1 , 1 )), ); const sold = results . filter (( r ) => r . status === ' fulfilled ' ). length ; const { rows : [{ stock }] } = await pool . query ( ' SELECT stock FROM products WHERE id = 1 ' ); const { rows : [{ count }] } = await pool . query ( ' SELECT count(*)::int AS count FROM orders ' ); expect ( sold ). toBe ( 10 ); expect ( count ). toBe ( 10 ); expect ( stock ). toBe ( 0 ); }); Run it against the naive version and it will fail. Use a pool larger than 1 so the requests genuinely interleave. (Timing-dependent tests can occasionally pass by luck, so run it several times, or raise the buyer count.) Fix 0: Let the database do it atomically Before reaching for locks, consider the simplest fix: move the check into the write . // ✅ Check and decrement in one atomic statement async function purchase ( productId : number , qty : number ) { return withTransaction ( async ( tx ) => { const res = await tx . query ( `UPDATE products SET stock = stock - $1 WHERE id = $2 AND stock >= $1` , [ qty , productId ], ); if ( res . rowCount === 0 ) throw new OutOfStockError (); // not enough stock (or no such product) await tx . query ( ' INSERT INTO orders (product_id, qty) VALUES ($1, $2) ' , [ productId , qty ]); }); } Why this works: a single UPDATE takes a row-level lock on the row it modifies. If a second transaction tries to update the same row, it waits for the first to commit or roll back. Under PostgreSQL's default READ COMMITTED isolation level, once the lock is released, the waiting statement re-checks its WHERE clause against the newly committed row . So request B re-evaluates stock >= 1 against the value A left behind (0) and updates nothing. Request A Request B UPDATE ... WHERE stock >= 1 → locks row, stock 1 → 0 UPDATE ... WHERE stock >= 1 → waits on A's lock COMMIT → re-checks: stock is 0, no match → rowCount = 0 → OutOfStock Two things make this solid: The decrement is relative ( stock = stock - $1 ), not an absolute value computed in the app. That's what avoids the lost update. The guard is part of the same statement , so there's no window between check and write. Add a final safety net at the schema level so a future bug can never produce negative stock: ALTER TABLE products ADD CONSTRAINT stock_non_negative CHECK ( stock >= 0 ); For many inventory systems, this is the whole answer. Locks, versions, and retries are for the cases where the logic between read and write is too complex to fit into a single UPDATE : pricing rules, multi-step validation, reservations that depend on other rows. Fix 1: Pessimistic locking ( SELECT ... FOR UPDATE ) Pessimistic locking assumes conflicts are likely, so it locks the row up front , before reading. Anyone else who wants the row waits. async function purchase ( productId : number , qty : number ) { return withTransaction ( async ( tx ) => { // Lock the row; concurrent transactions block here until we commit/rollback const { rows } = await tx . query ( ' SELECT stock, price_cents FROM products WHERE id = $1 FOR UPDATE ' , [ productId ], ); if ( rows . length === 0 ) throw new NotFoundError (); const { stock , price_cents } = rows [ 0 ]; // Arbitrary application logic is now safe: nobody can change this row under us if ( stock qty ) throw new OutOfStockError (); const total = computeTotalWithPromotions ( price_cents , qty ); await tx . query ( ' UPDATE products SET stock = stock - $1 WHERE id = $2 ' , [ qty , productId ]); await tx . query ( ' INSERT INTO orders (product_id, qty, total_cents) VALUES ($1, $2, $3) ' , [ productId , qty , total ], ); }); } withTransaction is the helper from earlier posts in this series: it acquires a client, issues BEGIN , runs your function, commits or rolls back, and always releases the connection. Now the read, the check, and the write are one critical section. This is the right tool when the logic between read and write can't be expressed as a single SQL statement. Pessimistic locking variants worth knowing -- Fail immediately if someone else holds the lock, rather than waiting SELECT ... FROM products WHERE id = $ 1 FOR UPDATE NOWAIT ; -- error 55P03 (lock_not_available) -- Skip locked rows (great for job queues and "claim the next available item") SELECT ... FROM tickets WHERE status = 'free' LIMIT 1 FOR UPDATE SKIP LOCKED ; You can also bound waiting with SET LOCAL lock_timeout = '2s' inside the transaction, so a stuck lock turns into a fast error instead of a pile-up. The costs of pessimistic locking Contention serializes your throughput. Every buyer of the same product queues behind the lock holder. For a flash-sale SKU, that's one-at-a-time processing. Long transactions are dangerous. The lock is held until COMMIT . If you call a payment API, send an email, or do any slow work while holding it, everything else waits, and you'll also pin a connection from your pool the whole time (see our post on pool starvation). Keep locked transactions short, and never do network I/O inside them. Deadlocks. If two transactions lock rows in opposite orders, Postgres detects the cycle and aborts one with error 40P01 . Avoiding deadlocks in multi-item orders A cart with several products locks several rows. If request A locks product 1 then 2, while request B locks 2 then 1, they deadlock. The fix is simple and effective: always acquire locks in a consistent order. async function purchaseCart ( items : { productId : number ; qty : number }[]) { // Sort so every transaction locks rows in the same order const ordered = [... items ]. sort (( a , b ) => a . productId - b . productId ); return withTransaction ( async ( tx ) => { for ( const { productId , qty } of ordered ) { const res = await tx . query ( ' UPDATE products SET stock = stock - $1 WHERE id = $2 AND stock >= $1 ' , [ qty , productId ], ); if ( res . rowCount === 0 ) throw new OutOfStockError ( productId ); // rolls back ALL items } await tx . query ( ' INSERT INTO orders ... ' ); }); } Notice this uses the atomic pattern from Fix 0 plus sorted ordering, and the transaction guarantees all-or-nothing: if the third item is out of stock, the first two decrements are rolled back. Even with consistent ordering, wrap your transactions in a retry for 40P01 (deadlock detected) and 40001 (serialization failure). They're rare, but they're expected, not exceptional. Fix 2: Optimistic locking (version column + retry) Optimistic locking assumes conflicts are rare , so it doesn't lock anything while you think. Instead it detects a conflict at write time and makes you try again. Add a version column: ALTER TABLE products ADD COLUMN version INTEGER NOT NULL DEFAULT 0 ; Read the row and its version without locking. When writing, include the version you saw in the WHERE clause and bump it: async function purchaseOptimistic ( productId : number , qty : number ) { const { rows } = await pool . query ( ' SELECT stock, version FROM products WHERE id = $1 ' , [ productId ], ); const { stock , version } = rows [ 0 ]; if ( stock qty ) throw new OutOfStockError (); const res = await pool . query ( `UPDATE products SET stock = $1, version = version + 1 WHERE id = $2 AND version = $3` , [ stock - qty , productId , version ], ); if ( res . rowCount === 0 ) throw new ConflictError (); // someone else changed the row since we read it // ...create order (in the same transaction in real code) } If another request modified the row between our read and write, its version bump means our WHERE version = $3 matches nothing, rowCount is 0, and we know our view of the world was stale. The caller then retries from the top with fresh data. The retry loop is not optional async function withRetry T > ( fn : () => Promise T > , maxAttempts = 5 ): Promise T > { for ( let attempt = 1 ; ; attempt ++ ) { try { return await fn (); } catch ( err : any ) { const retryable = err instanceof ConflictError || err . code === ' 40001 ' || // serialization_failure err . code === ' 40P01 ' ; // deadlock_detected if ( ! retryable || attempt >= maxAttempts ) throw err ; // Exponential backoff with full jitter, so colliding requests spread out const delay = Math . random () * Math . min ( 200 , 10 * 2 ** attempt ); await new Promise (( r ) => setTimeout ( r , delay )); } } } await withRetry (() => purchaseOptimistic ( 1 , 1 )); Cap the attempts, and add jitter. Without jitter, colliding requests retry in lockstep and collide again. When optimistic locking shines (and when it doesn't) Good fit: Low contention: collisions are occasional (many different products, each rarely bought concurrently) Long "think time" between read and write, where holding a lock would be unacceptable. For example, a user editing a record in a UI: send the version with the form and reject a stale save (the HTTP version of this is ETag / If-Match ) You don't want to hold database locks or connections while waiting on slow things Poor fit: Hot rows. If 500 people want the same last 10 units, most attempts fail and retry, burning CPU and database round trips on work that gets thrown away. Throughput can collapse under heavy contention. Anything where retrying isn't safe unless you've made the surrounding side effects idempotent (don't charge a card inside a retried block) Comparing the approaches Atomic conditional UPDATE Pessimistic ( FOR UPDATE ) Optimistic (version + retry) Locks held Only during the statement From the read until commit None while reading Handles complex logic between read and write No (must fit in SQL) Yes Yes Behavior under contention Queues briefly, stays correct Queues (serialized) Retries (can thrash) Failure mode Out-of-stock ( rowCount 0 ) Waiting, timeouts, deadlocks Conflicts, retry storms Retry logic needed No Only for deadlock/timeout Yes Best for Counters, stock decrements High contention, multi-step logic Low contention, long think time Complexity Lowest Medium Highest A practical decision guide: Can the rule be expressed as UPDATE ... SET x = x - n WHERE x >= n ? Do that. It's the simplest and handles contention well. Is the logic complex and contention likely (flash sales, popular SKUs)? Pessimistic , with short transactions and ordered locking. Is contention rare, or is there a long gap between read and write (user edits, multi-step approvals)? Optimistic . A word on isolation levels PostgreSQL defaults to READ COMMITTED , and everything above is designed to be correct there. You can also raise the isolation level: await client . query ( ' BEGIN ISOLATION LEVEL SERIALIZABLE ' ); At REPEATABLE READ and SERIALIZABLE , PostgreSQL detects conflicting concurrent updates and aborts one transaction with 40001 rather than letting it proceed on stale data. That gives you correctness without hand-placed locks, but you must catch 40001 and retry the whole transaction. It's the same retry discipline as optimistic locking, enforced by the database. The trade-off is more aborted transactions under contention, so test with realistic concurrency before adopting it broadly. When one row is too hot: scaling past a single counter If a single product row is the center of a stampede, even the best-behaved locking serializes on it. Options when that becomes your bottleneck: Reservations with expiry. Decrement stock into a reserved count when a user enters checkout, with a reserved_until timestamp. Release expired reservations with a background job. Also keeps the lock window short and avoids selling stock to people who never finish paying. An append-only inventory ledger. Record +N / -N movements and derive stock by summing, with periodic roll-ups. Inserts don't contend on one row, and you get an audit trail for free. Sharded counters. Split stock for a hot SKU across several rows (for example, 10 buckets) and have each purchase pick one bucket. It's more complex to read the total and to handle "bucket empty, try another." Serialize in a queue. Route all purchases for a hot SKU through a single consumer (for example, a queue partitioned by product ID). The queue gives you ordering and backpressure, and the database sees no contention. Advisory locks. pg_advisory_xact_lock(key) lets you lock a logical resource that isn't a single row. Useful, but it's still a lock, with the same hold-time and deadlock considerations. Reach for these only when measurements say the simple approaches aren't enough. Don't forget idempotency Network retries and double-clicks mean the same purchase may arrive twice. Locking prevents overselling, but not double-ordering by one customer. Add an idempotency key with a unique constraint: ALTER TABLE orders ADD COLUMN idempotency_key TEXT ; CREATE UNIQUE INDEX orders_idem_idx ON orders ( idempotency_key ); const res = await tx . query ( `INSERT INTO orders (product_id, qty, idempotency_key) VALUES ($1, $2, $3) ON CONFLICT (idempotency_key) DO NOTHING` , [ productId , qty , key ], ); if ( res . rowCount === 0 ) { // Already processed. Return the existing order instead of decrementing stock again. } Insert the order (and check the conflict) before decrementing stock, inside the same transaction, so a duplicate request rolls back cleanly without touching inventory. Checklist ✅ Use relative updates ( stock = stock - n ), never write back a value computed from an earlier read ✅ Put the guard in the WHERE clause ( AND stock >= n ) and check rowCount ✅ Add CHECK (stock >= 0) as a last line of defense ✅ Keep locking transactions short , with no HTTP calls or slow work inside ✅ Lock multiple rows in a consistent order ✅ Retry on 40001 and 40P01 , with a cap, backoff, and jitter ✅ Make order creation idempotent ✅ Keep a concurrency test (N buyers, M units) in CI Key takeaways Read-then-write races oversell inventory. The gap between the check and the update is the bug. The simplest fix is usually an atomic conditional UPDATE , with the check and the decrement in one statement. Pessimistic locking ( FOR UPDATE ) serializes access up front. Use it for complex logic under high contention, but keep transactions short and lock in a consistent order. Optimistic locking (version column) detects conflicts at write time. It's great under low contention, and it needs a bounded retry loop with jitter. Pick based on contention and logic complexity , not preference. Hot rows punish optimistic locking, and rare conflicts make pessimistic locking needless overhead. Test with real concurrency. A test that fires 50 buyers at 10 units will catch what code review won't. How do you handle hot SKUs in your system? Share your approach in the comments. Further reading: the PostgreSQL docs on explicit locking and transaction isolation .
DEV CommunityThe Giantsread at source
Compose Multiplatform Rendering Pipeline: How Skia and CoreGraphics Interact on iOS Under Memory Pressure
--- title : " CMP iOS Rendering: How Skia and Metal Interact Under Memory Pressure" published : true description : " Deep dive into Compose Multiplatform's Skia-to-Metal rendering on iOS, GPU context switches at UIKitView boundaries, and the compositing decisions that spike memory on 3GB devices." tags : kotlin, ios, mobile, performance canonical_url : https://mvpfactory.co/blog/cmp-ios-rendering-skia-metal-memory-pressure --- ## What you will learn By the end of this article you will understand why a Compose Multiplatform app that passes QA on the simulator drops frames on iPhone XR in production. Specifically: how CMP's Skia canvas delegates to Apple's Metal GPU, where the `UIKitView` boundary forces expensive GPU context switches, and which compositing decisions trigger memory spikes on devices with 3GB RAM — with real measurements from a production app. ## Prerequisites - Working knowledge of Compose Multiplatform and `ComposeUIViewController` - Xcode installed with access to Frame Debugger and Instruments - A real device with A12-class silicon for testing (iPhone XR is your target) --- ## Step 1: Understand how CMP gets pixels onto an iOS screen Compose Multiplatform does not use UIKit's native rendering stack. It embeds a Skia canvas backed by a `CAMetalLayer` , so every composable you write gets rasterized by Skia and submitted to Metal as a command buffer. The host `UIViewController` hands ownership of a `MetalView` to the CMP runtime, which drives its own render loop independent of UIKit's display link. The fundamental constraint: one Skia context, one Metal device, one command queue, for the entire CMP surface. kotlin // CMP iOS entry point (simplified) ComposeUIViewController { App() // Your composables render entirely within Skia's canvas } That model is clean and fast for pure-Compose screens. The trouble starts the moment you introduce native UIKit components. ## Step 2: Understand the UIKitView boundary Here is the gotcha that will save you hours. When you embed a native component using `UIKitView`, CMP must composite two worlds: Skia's Metal-backed texture and UIKit's `CALayer` tree. iOS handles this via layer compositing — the system compositor (`WindowServer`) blends the `CAMetalLayer` with the native `CALayer` hierarchy. Each `UIKitView` insertion creates a compositor boundary. The GPU has to flush Skia's current render pass, submit it, then let the system compositor blend the result with the native layer. That is an extra roundtrip through the display pipeline on every frame. On A14 and newer silicon this cost is nearly imperceptible at 60fps. On A12-class chips with 3GB RAM, under concurrent memory pressure from background processes, these flushes can stall the Metal command queue long enough to drop frames. ## Step 3: Audit these four compositing patterns Let me show you a pattern I audit in every CMP iOS project before shipping. | Trigger | Why it allocates | Mitigation | |---|---|---| | Non-opaque root layer | Forces an offscreen MSAA buffer | Set `background(Color.Black)` or a fully opaque fill | | `clip { }` with non-rectangular shape | Skia allocates a stencil buffer | Prefer `clip(RoundedCornerShape)` — often batched | | `graphicsLayer { alpha = ... }` on large surfaces | Promotes layer to offscreen texture | Scope alpha to leaf nodes, not containers | | Nested `UIKitView` in a `LazyColumn` | Repeated compositor handoffs per row | Virtualize or replace with a Skia-native equivalent | In a production app with a mixed Skia/UIKit screen, auditing these four patterns cut peak IOSurface allocations by ~25–35% on 3GB devices. The biggest gains came from eliminating offscreen MSAA buffers — memory the OS does not aggressively reclaim under pressure. ## Step 4: Profile with Frame Debugger and Metal System Trace Here is the minimal setup to get this working. **Frame Debugger:** Launch via Product → Profile → GPU Frame Capture and expand the render pass list. You are looking for unexpected `Offscreen Pass` entries — each one is a compositing cost you probably did not intend. Check the `Attachments` column: MSAA resolve targets indicate non-opaque layer promotions. **Metal System Trace:** Use the `GPU` instrument track alongside `VM Tracker`. Correlate `IOKit` memory allocations with your compositing operations. A spike in `IOSurface` allocations during list scroll is the signature of repeated offscreen buffer creation. The docs do not mention this, but you can force a GPU capture from code during testing: swift MTLCaptureManager.shared().startCapture(with: captureDescriptor) Pair this with the Allocations instrument filtered to `IOSurface` and `MTLTexture` to isolate Skia-owned GPU memory from UIKit's. --- ## Gotchas **The simulator hides everything.** GPU context switches under memory pressure only appear on real hardware. Keep an iPhone XR (A12 Bionic, 3GB RAM) in your pre-release checklist — it is your most reliable canary. **`graphicsLayer` on containers is the biggest offender.** Every `alpha`, `shadowElevation`, or `renderEffect` on a container composable is a potential offscreen buffer. Scope these modifiers to leaf-level composables. **Scatter kills performance, batching saves it.** Where native UIKit components are unavoidable, group them at screen edges rather than scattering them through Skia-rendered content. This minimises compositor handoffs per frame. **Set an Offscreen Pass budget.** Anything above single digits on a standard screen warrants investigation before you ship. --- ## Conclusion CMP's rendering pipeline is fast and mostly gets out of your way — until it doesn't. The compositing graph is not where most engineers spend their attention, and that is exactly why it bites them in production on devices their team never tested. Audit your `graphicsLayer` usage, minimise `UIKitView` boundaries on high-frequency screens, and add GPU Frame Capture to your pre-release checklist. Further reading: [GPU Frame Capture docs](https://developer.apple.com/documentation/metal/debugging_tools/capturing_gpu_command_data_programmatically) and the [Metal System Trace instrument reference](https://developer.apple.com/documentation/instruments).
DEV CommunityThe Giantsread at source
Improving Visibility in Automotive Manufacturing with AI and IoT
Modern automotive manufacturing involves thousands of components, multiple assembly stations, complex supply chains, and interconnected production systems. Keeping track of every vehicle, component, machine, and production activity is a significant operational challenge. In many manufacturing environments, data is distributed across different systems. Production teams may use one platform to monitor assembly operations, another to manage inventory, and separate tools for equipment monitoring and quality control. This fragmentation makes it difficult to obtain a unified, real-time view of factory operations. Artificial Intelligence (AI), the Internet of Things (IoT), RFID, and real-time location systems (RTLS) can help bridge this gap by connecting physical manufacturing processes with digital systems. In this article, we'll explore how these technologies work together to improve manufacturing visibility, strengthen vehicle traceability, and support smarter automotive production. Understanding the Visibility Problem Manufacturing visibility is the ability to determine the status, location, and movement of assets and products throughout the production lifecycle. In an automotive factory, this may include: Tracking vehicles across assembly stations. Monitoring work-in-progress (WIP). Locating components and production tools. Recording manufacturing events. Monitoring equipment health. Retrieving vehicle-specific quality records. Without reliable visibility, teams may rely on manual updates, disconnected applications, or delayed reports. This can lead to inconsistent production data, difficulty identifying bottlenecks, and slower responses to operational problems. From a software engineering perspective, the challenge is not simply collecting more data. It's designing a reliable system that transforms events from physical operations into meaningful, accessible information. Using RFID and RTLS for Asset Tracking Radio-frequency identification (RFID) and real-time location systems (RTLS) are useful technologies for tracking assets in industrial environments. Although they are sometimes discussed together, they solve different tracking problems. RFID RFID uses radio waves to identify tagged objects through compatible readers. In automotive manufacturing, RFID can help identify vehicles, components, containers, and tools as they pass through designated detection points. For example, when a tagged vehicle enters an assembly area, an RFID reader can capture its identifier and generate a tracking event. A simplified event might look like this: { "assetId": "VEH-10452", "eventType": "STATION_ENTRY", "stationId": "ASSEMBLY-03", "timestamp": "2026-10-13T10:15:30Z", "source": "RFID_READER_07" } This event can be sent to a backend service, stored in a database, and used to update the vehicle's latest known production location. RTLS RTLS technologies provide location information using technologies such as ultra-wideband (UWB), Bluetooth Low Energy (BLE), or other suitable positioning methods. Depending on the implementation, an RTLS solution can estimate an asset's location within a facility rather than only recording its passage through a designated detection point. The appropriate choice depends on several factors: Required location accuracy. Factory layout and physical obstructions. Tracking frequency. Infrastructure and maintenance costs. Environmental conditions. A useful engineering principle is to select the least complex technology that satisfies the actual business requirement. If the objective is to record when a vehicle enters a station, RFID may be sufficient. If the objective is to locate mobile equipment within a large facility, an RTLS solution may be more appropriate. Building VIN-Based Traceability Every vehicle has a Vehicle Identification Number (VIN), which can serve as a unique identifier for connecting manufacturing records. A traceability system can associate the VIN with production events, assembly milestones, inspection results, and relevant component records. For example, a vehicle's production history might contain events such as: [ { "vin": "EXAMPLEVIN12345678", "event": "BODY_ASSEMBLY_COMPLETED", "station": "BODY-02", "timestamp": "2026-10-13T08:30:00Z" }, { "vin": "EXAMPLEVIN12345678", "event": "QUALITY_INSPECTION_PASSED", "station": "QUALITY-01", "timestamp": "2026-10-13T09:45:00Z" } ] Note: The VIN shown here is illustrative, not a verified vehicle identifier. With this information, an authorized user could query the system to retrieve a vehicle's production history. For example: SELECT vin, event, station, timestamp FROM production_events WHERE vin = 'EXAMPLEVIN12345678' ORDER BY timestamp ASC; This approach makes it easier to reconstruct the sequence of recorded manufacturing activities. However, a production-grade traceability system needs more than a simple database query. Important considerations include: Consistent vehicle and component identifiers. Reliable event timestamps. Duplicate-event handling. Data validation. Auditability. Access control. Retention and privacy requirements. It's also important to distinguish between a vehicle's latest recorded location and its guaranteed current physical location. If tracking events are delayed or missed, the two may differ. Designing an Event-Driven Manufacturing Architecture A connected manufacturing system often receives events from many sources, including RFID readers, PLCs, IoT gateways, inspection stations, and manufacturing execution systems. An event-driven architecture can help process these events without tightly coupling every device to every application. A simplified architecture looks like this: +-----------------------------+ | Factory Devices | | RFID | RTLS | PLC | Sensors | +--------------+--------------+ | v +-----------------------------+ | Edge Gateway | | Validation and Normalization| +--------------+--------------+ | v +-----------------------------+ | Messaging Layer | | MQTT / Kafka / Other Broker | +--------------+--------------+ | v +-----------------------------+ | Backend Services | | Tracking | Traceability | | Rules | Analytics | +--------------+--------------+ | v +-----------------------------+ | Data Storage | | Events | Asset State | | Production History | +--------------+--------------+ | v +-----------------------------+ | Applications and Dashboards | | MES | ERP | Quality | APIs | +-----------------------------+ This is a conceptual architecture, not a requirement to use every component. Why use an event-driven approach? Loose coupling: Devices can publish events without knowing which applications consume them. Scalability: Additional consumers can be introduced as tracking and analytics requirements grow. Integration flexibility: Different applications can process the same event stream for different purposes. Improved observability: Event-processing systems can expose metrics such as message latency, processing failures, and throughput. Technologies such as MQTT and Apache Kafka may be useful in different parts of this architecture, but they are not interchangeable in every scenario. MQTT is commonly used for lightweight messaging between devices and connected applications. Kafka is designed for distributed event streaming and durable event processing at scale. The right choice depends on the deployment environment, reliability requirements, infrastructure, and existing technology stack. Using Industrial IoT and AI for Equipment Monitoring Unexpected equipment failures can interrupt production and create costly delays. Industrial IoT can help by collecting operational data from sensors and connected machinery. Depending on the equipment, measurements may include: Temperature. Vibration. Pressure. Current consumption. Machine operating state. Cycle time. These measurements can be processed to identify abnormal operating conditions. For example, an anomaly-detection system might compare current vibration measurements with historical patterns for a particular machine. A simplified processing flow could be: Sensor Data | v Data Validation | v Feature Extraction | v Anomaly Detection | v Alert Generation | v Maintenance Investigation AI models can help detect patterns that are difficult to identify through simple threshold rules. However, not every equipment-monitoring problem requires machine learning. A temperature threshold, a rule-based alert, or a statistical control chart may be sufficient for a particular use case. Machine learning becomes more useful when the problem benefits from identifying complex patterns and sufficient high-quality training data is available. A production-ready predictive maintenance system should also account for: Sensor failures and missing data. False-positive alerts. Model drift. Equipment-specific behavior. Validation against real maintenance outcomes. Human review and escalation procedures. The goal is not to generate more alerts. It's to identify meaningful problems early enough for teams to respond effectively. Integrating ERP, MES, and IoT Platforms Manufacturing visibility becomes more valuable when information can flow between operational systems. ERP platforms typically support business processes such as inventory, purchasing, and production planning. MES platforms focus on manufacturing execution, including production activities, work orders, and process records. IoT platforms collect and process information from connected devices and industrial equipment. These systems have different responsibilities, so integration should preserve clear ownership of data. For example: Information Potential System of Record Production orders ERP Actual production execution MES Sensor measurements IoT platform or time-series storage Vehicle tracking events Tracking service Inspection results Quality management system Consolidated production visibility Reporting or application layer The exact division depends on the organization's existing architecture. Common integration challenges Inconsistent identifiers: A vehicle or component may be represented differently across systems. Event ordering: Messages may arrive late or out of sequence. Duplicate messages: Network retries can cause the same event to be delivered more than once. Data ownership: Multiple systems may disagree about the authoritative value of a field. Connectivity problems: Factory networks and remote systems may experience interruptions. These problems should be addressed at the architectural level rather than left entirely to individual application developers. For example, event consumers should be designed to handle duplicate messages safely where the delivery model permits them. Systems should also retain sufficient timestamps and source metadata to investigate delayed or inconsistent events. Data Quality Is the Foundation of Manufacturing AI AI and analytics depend on the quality of the data they receive. A model cannot reliably predict equipment failures if sensor readings are frequently missing, timestamps are inaccurate, or the training data does not represent normal operating conditions. Similarly, a traceability application cannot provide a complete production history when important events are never recorded. A robust data-quality strategy should include: Validation: Reject or quarantine malformed events. Normalization: Standardize identifiers, timestamps, units, and event types. Deduplication: Detect repeated events where appropriate. Monitoring: Track missing data, processing delays, and unusual event volumes. Reconciliation: Compare digital records against trusted operational sources. Governance: Define ownership, access rules, and retention policies. Manufacturers should also distinguish between real-time operational data and historical analytical data. Operational systems may prioritize low latency and current state, while analytics systems may prioritize historical completeness and reproducibility. Both are important, but their requirements are not always identical. Starting with a Small, Measurable Pilot A full-scale smart manufacturing transformation can be expensive and technically complex. A focused pilot is often a better starting point. Consider a project designed to improve visibility into work-in-progress vehicles between two assembly stations. The pilot might include: RFID readers at selected tracking points. A service that validates and processes tracking events. A database for event history. An API for retrieving the latest known vehicle status. A dashboard showing vehicle movement and missing updates. Before deployment, establish baseline metrics such as: Average time required to locate a vehicle. Percentage of expected tracking events successfully recorded. Delay between physical movement and digital status updates. Number of manual location investigations. Frequency of missing or duplicate records. After deployment, compare the results with the baseline. This approach helps answer a critical question: Does the system solve a real operational problem? It also exposes integration, connectivity, and data-quality issues before the architecture is expanded across the facility. Where Automotive Manufacturing Visibility Is Heading As manufacturing systems become more connected, the opportunity extends beyond simply locating vehicles or monitoring machines. Combining production events, equipment telemetry, quality records, and historical data can provide a more comprehensive view of factory operations. Potential applications include: More responsive production dashboards. Improved component and vehicle traceability. Earlier identification of production bottlenecks. Better-informed maintenance planning. Automated detection of unusual process behavior. More efficient quality investigations. Digital twins and advanced analytics may also help manufacturers compare actual operations with expected production behavior. However, these capabilities depend on reliable integration between physical assets, operational systems, and analytical applications. A connected factory is not created by introducing a single technology. It emerges from a collection of systems that exchange trustworthy data and support well-defined operational workflows. Conclusion Improving visibility in automotive manufacturing is both an operational challenge and a systems-engineering problem. RFID and RTLS can help track assets. VIN-based traceability can connect vehicles with manufacturing records. Industrial IoT can provide equipment telemetry. AI can help identify patterns and anomalies. Event-driven architectures can connect these capabilities with MES, ERP, and quality systems. The technical challenge is to bring these components together without compromising data quality, reliability, security, or maintainability. For engineering teams, the most effective approach is to begin with a clearly defined use case, design for reliable event processing, measure real-world outcomes, and expand gradually. Ultimately, the value of a connected manufacturing system comes not from the volume of data it collects, but from how effectively that data supports better decisions on the factory floor. What would you prioritize when designing a connected automotive manufacturing platform: real-time tracking, event-driven integration, data quality, or AI-powered equipment monitoring? Share your thoughts in the comments.
DEV CommunityThe Giantsread at source
Computer Vision for Beginners: From Pixels to Predictions
What I learned in my first computer vision : how images become numbers, how filters find edges, and how classification, detection and segmentation differ. With my own results, including where the models failed. I used to think computer vision meant a computer "seeing" a picture the way I do. It doesn't. After my first hands-on session in the kLab TekHer AI Program (Cohort 2), I understand why, and I learned it best by running the code and testing my own photos. This post follows the same path as the session: pixels → filters → classification → detection → segmentation → failure cases. Everything here comes from a Python notebook I ran in VS Code, with the "Try it yourself" exercises done by hand. What you will learn How a computer stores an image How a filter finds edges, and why that matters for CNNs The difference between classification, detection and segmentation Where pretrained models fail, with my own results What is computer vision? Computer vision lets computers get meaning from images and video. Almost every vision system answers one or more of three questions: Question Example What is in the image? A cat, a cassava leaf Where is it? Which pixels, which part What is happening? A person crossing the road Humans and computers are good at different things. We learn from years of seeing and need few examples. A computer needs millions of labelled images, but it then works at huge speed and scale. Its main weakness is anything unlike its training data, and we will see that later. An image is a grid of numbers A computer never sees "a bus". It receives a grid of rows × columns × 3 colour values (red, green, blue), each from 0 to 255. Why 255? Each value uses 8 bits, and 8 bits give 2⁸ = 256 possible values. python import numpy as np from PIL import Image img = np.array(Image.open("photo.jpg").convert("RGB")) print(img.shape) # (height, width, 3): height first, then width print(img.dtype) # uint8: whole numbers from 0 to 255 print(img[100, 400]) # one pixel: [R, G, B] A small 400 × 600 photo holds 400 × 600 × 3 = **720,000 numbers**. A phone photo holds more than 30 million. The core challenge of computer vision is going from these numbers to meaning. A colour image is three grids Each pixel has a red, a green and a blue value. Showing each channel on its own makes this visible: Strong colour means a high value (near 255) and pale means a low value (near 0). I also removed the red channel to see what happens: python no_red = img.copy() # copy, so the original is not damaged no_red[:, :, 0] = 0 # set every red value to 0 Pure red areas became black, because (255, 0, 0) turns into (0, 0, 0). White areas became cyan, because white without red is green plus blue. 2. Filters: finding edges by hand A filter(or kernel) is a small grid of weights. For every pixel, you multiply it and its neighbours by the weights and add the results. That sum is the new pixel value. Then the filter slides across the whole image. Here are three filters: python blur = np.ones((5, 5)) / 25 # average of 25 neighbours sobel_x = np.array([[-1, 0, 1], [-2, 0, 2], [-1, 0, 1]]) # right minus left: vertical edges sobel_y = sobel_x.T # bottom minus top: horizontal edges Why does `sobel_x` find vertical edges? Look at two 3×3 patches: | Patch | Left side | Right side | Result | |---|---|---|---| | Flat: every pixel is 100 | 100 × (−1 −2 −1) = −400 | 100 × (1 + 2 + 1) = +400 | **0**, no edge | | Edge: left is 0, right is 200 | 0 | 200 × 4 = +800 | **800**, an edge | So flat areas become black and edges become bright. The weights of a Sobel filter add up to 0, which is why flat areas disappear. Blur and sharpen weights add up to 1, so the overall brightness stays the same. I also tried my own kernels. My first sharpen result looked flat grey because the values went outside 0–255. Clipping them with `np.clip(result, 0, 255)` fixed it. The big idea: a CNN learns its own filters A convolutional neural network (CNN) does exactly this multiply-and-add. The only difference is that nobody chooses the weights. Training learns them from labelled data. Researchers who visualise trained CNNs find a clear pattern: Pixels → edges → textures → objects Early layers learn edges and colours, middle layers learn textures and parts like eyes or wheels, and the last layers respond to whole objects. 3. Classification: one label for the whole image I loaded a small pretrained model that picks from 1,000 ImageNet classes and returns a confidence for each. python from ultralytics import YOLO classifier = YOLO("yolo11n-cls.pt") r = classifier("photo.jpg", verbose=False)[0] for idx in r.probs.top5: print(r.names[idx], f"{r.probs.data[idx].item():.1%}") I tested it on photos from my own context in Rwanda, and the results taught me more than the sample images did: Photo Top label Confidence agaseke(woven basket) vase 35.1% umukenyero (wrapped cloth) sarong 78.7% A photo of me next to a car maillot (tights 17.3% Three lessons: 1. The model always picks something. Its final step, softmax, forces the 1,000 probabilities to add up to 100%, so it can never say "I don't know." 2.High confidence is not correctness. The sarong answer was 78.7% sure and only roughly right. The model does not know the Rwandan name or meaning. 3. There is no "person" class in ImageNet.** On my photo, the model looked at the dress and returned clothing labels. 4. Object detection: what and where A classifier gives one label. A **detector** draws a box around each object it knows (80 everyday categories from the COCO dataset) and gives a confidence for each. python detector = YOLO("yolo11n.pt") r = detector("photo.jpg", conf=0.4, verbose=False)[0] for box in r.boxes: x1, y1, x2, y2 = box.xyxy[0].int().tolist() print(r.names[int(box.cls)], f"{float(box.conf):.0%}", (x1, y1), (x2, y2)) Each box has a corner position, where x counts from the left and y counts from the top. Detection on the sample bus photo: a box, a label and a confidence for each object. 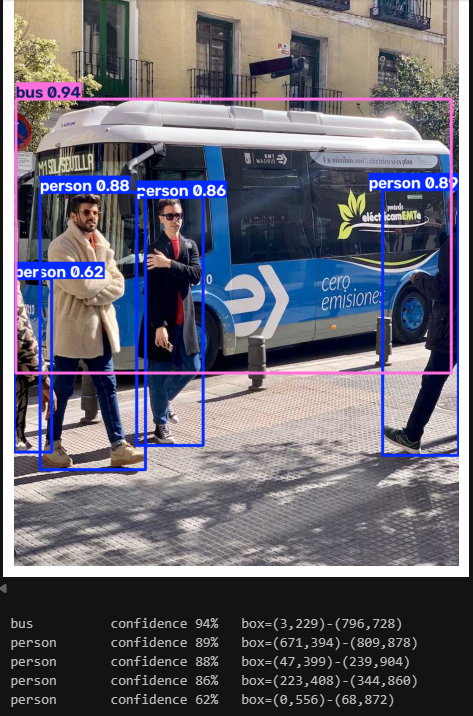 On my own photo the detector found person (94%) and car (70%). The car was less certain because I was standing in front of it and hiding part of it. The confidence threshold is a choice you make The `conf` setting is the minimum confidence a box needs to be shown. Threshold Misses real objects False alarms Low (0.1) fewer more High (0.9) more fewer This is the same trade-off as in medical screening: a low threshold misses fewer real cases but raises more false alarms. Why is YOLO fast? YOLO stands for You Only Look Once. Older detectors first proposed many regions and then classified each one, which was accurate but slow. YOLO looks at the whole imag once and predicts every box, label and confidence in a single pass. That makes it fast enough for live video and small devices. 5. Segmentation: which pixels belong to which object Segmentation goes one step further and gives every object a **mask**, a grid of 0s and 1s where 1 means "this pixel belongs to the object." python segmenter = YOLO("yolo11n-seg.pt") r = segmenter("photo.jpg", conf=0.4, verbose=False)[0] for mask, c in zip(r.masks.data, r.boxes.cls): print(r.names[int(c)], int(mask.sum()), "pixels") 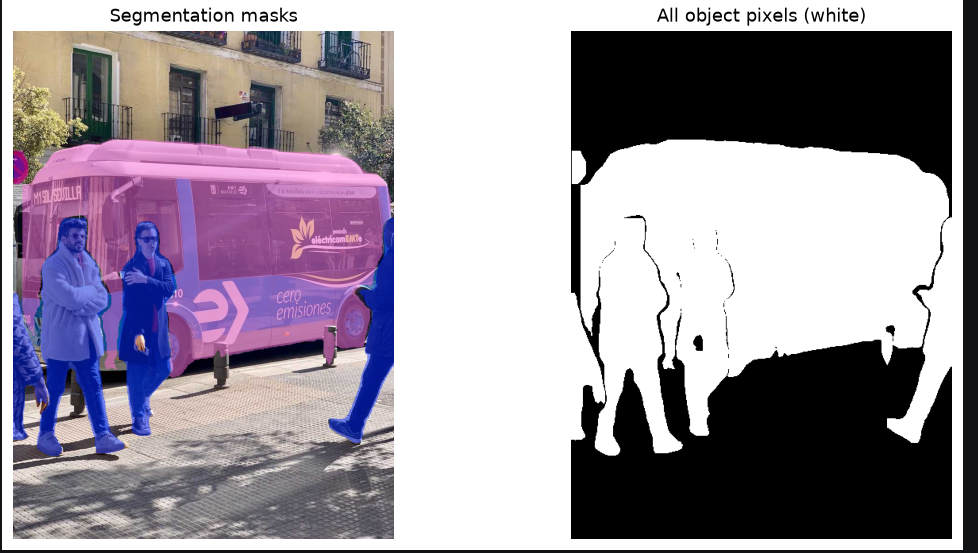 Every pixel of each object is labelled, not just a box around it. There is a neat trick here: **the mean of a grid of 0s and 1s is the fraction of 1s.** One line of code tells you what share of the image an object covers. The same idea measures building areas in satellite images, or a tumour in a scan. One photo, three tasks Task Question it answers Output Classification What is this picture about? One label Detection What is here, and where? A box per object Segmentation Which exact pixels? A mask per object More detailed outputs need more detailed training labels, and those cost more to create. 6. When models fail This was my favourite part. A model only knows what it was trained on, so I made harder versions of my photo and ran the detector on each. 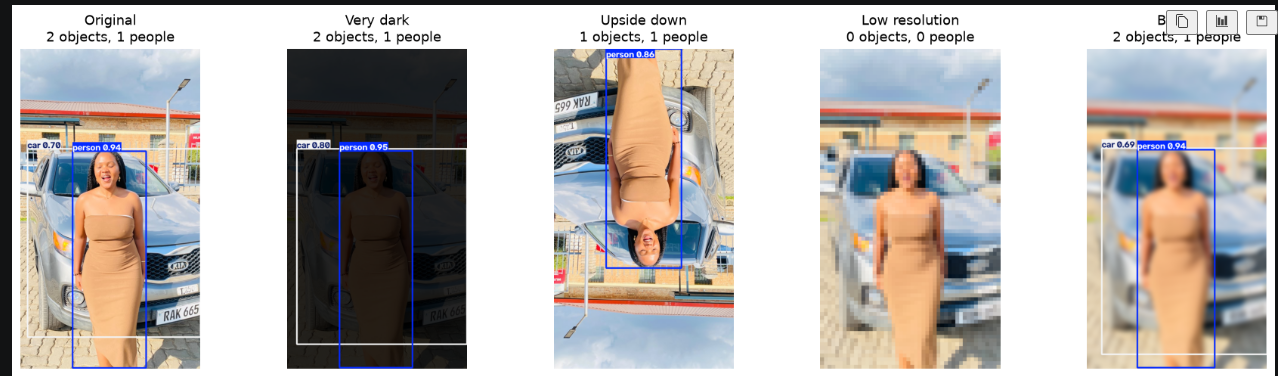 These are my own results on my photo: Version Objects found What happened Original 2 person 94%, car 70% Very dark 2 person 95%, car 80%: no damage Upside down 1 person 86%, car lost Low resolution (48 px wide) 0 found nothing Blurry 2 person 94%, car 69% almost no damage What stood out: Low resolution broke the detector completely. The tiny, blocky image removed almost all detail. The dark photo did not hurt the detector, but the classifier on the same dark photo changed its top answer to "crutch" (11.9%). Different models cope with different problems. Rotation hurt. When I turned the photo sideways, confidence fell, the same person appeared in two boxes, and the more confident box was the less accurate one. The pattern is simple: models fail on conditions they rarely saw in training. Why this matters in Africa These models were trained mostly on photos from Europe, North America and Asia. My agaseke became a "vase". Other risks I would check are local clothing, unpaved roads, moto-taxis, strong sunlight and low-quality phone photos. I have not tested all of these, so I treat them as risks, not proven results. The same technology is already used across the continent. The session slides listed examples such as: Agriculture: a farmer photographs a cassava leaf and an app names the disease, even offline -Health: software scores chest X-rays to decide who gets a TB lab test - Conservation:** smart camera traps alert rangers within minutes - Mapping: models outline every building from satellite images -Accessibility:a wearable vision assistant built in Kigali that describes objects and text The fix for the failures above is local data plus transfer learning: start from a pretrained model and train it a little more on local images, so it can learn to say "agaseke" instead of "vase". Key takeaways 1. An image is numbers: height × width × 3. 2. Filters find patterns, and CNNs learn the filters themselves. 3. Classification gives one label, detection adds location, and segmentation labels every pixel. 4. Confidence is not correctness. 5. Models fail on what they have not seen, so local data matters. What is next for me: building my own image classifier on local data, with an honest test set. If you are learning computer vision too, try the exercises yourself. Predicting the result before running the code taught me the most. Thanks for reading!
Hacker News: Show HNLibraries, Frameworks, etc.read at source
Show HN: What to Wear in NYC Today
Comments
Hacker News Front PageThe Giantsread at source
A Book That Will Never Be Read
Hacker News: Show HNLibraries, Frameworks, etc.read at source
Show HN: Virtual machines that live in your menu bar [macOS 27]
Comments
Hacker News Front PageThe Giantsread at source
New Apple TV 4K
Hacker News: Show HNLibraries, Frameworks, etc.read at source
Show HN: A coloring book where your drawings come alive and walks into a world
Comments
AbduzeedoMulti Author Blogsread at source
Erik Gustafsson — Editorial Design by Lundgren+Lindqvist
Lundgren+Lindqvist designed the monograph for Erik Gustafsson, shaping an editorial design defined by darkroom pacing and tactile materiality. Berlin-based Swedish artist Erik Gustafsson created Pause...
Hacker News Front PageThe Giantsread at source
Apple HomeView
Hacker News: Show HNLibraries, Frameworks, etc.read at source
Show HN: Vaguely Right, a Jev-based daily game – submit a clue to hit the target
Comments
Hacker News: Show HNLibraries, Frameworks, etc.read at source
Show HN: Glossdex – semantic search that returns nothing when nothing matches
Comments
Hacker News Front PageThe Giantsread at source
BB(10) > Graham's Number
Hacker News Front PageThe Giantsread at source
A Dynamic and Distributed Virtual GPU Cloud Built on Idle Apple Silicon Devices
Bram.usMore Front-end Bloggers5 min read
Introducing css-typed-om, a complete and WPT-tested polyfill for CSS Typed OM
Being a big fan of the CSS Typed OM , I’ve wanted a proper polyfill for it for years. Just before my summer vacation back in July, with the help of Gemini/Antigravity, I finally built one: css-typed-om .
Flavio CopesMore Front-end Bloggersread at source
A deep dive into LangChain and LangGraph
Learn LangChain and LangGraph with TypeScript: models, prompts, tools, agents, memory, streaming, RAG, graphs, persistence, and human approval.
HeyDesignerDeveloper/Designer Newsread at source
Craft: A collection of design engineering concepts
The dock on Mac, from OS 10 to macOS 27, How to present a proposal to a client (video), Murmuration for growing design teams, New to the web platform in September .
The Mozilla BlogBrowsers, engines, etc.4 min read
Mozilla introduces Firefox Enterprise
Institutions are recalculating who controls the technology they rely on. Mozilla has an independent option to offer. For years, organizations consolidated technology around a small number of providers to make things simpler. Fewer systems. Tighter integrations. More economies of scale. But that consolidation went well beyond technology. It consolidated dependency, too. The resulting risks have […] The post Mozilla introduces Firefox Enterprise appeared first on The Mozilla Blog .
Auth0 BlogCompany/Startup Blogsread at source
Introducing the Auth0 SDK for TanStack Start
Meet the new Auth0 SDK for TanStack Start and learn how to use it to add authentication to your apps.
AbduzeedoMulti Author Blogsread at source
Shake-it Mixer: Inside OlssønBarbieri Packaging Design
OlssønBarbieri crafted a refined packaging design for Shake-it Mixer, pairing custom fluted glass with 19th-century medicinal labels. Home mixology often relies on artificial cordials in dull plastic ...
Engineering at MetaCompany/Startup Blogs11 min read
OCP Summit 2026: Powering AI with Open Innovations in Scale-Up, Scale-Out, and Scale-Across Networks
At the 2026 Open Compute Project Global Summit, Meta is sharing the next generation of open networking infrastructure, including: Our first liquid-cooled network rack (IcePack), and 102.4T switch platform (IceCube). Flattened Planar Fabric (FPF), a multiplane backend scale-out fabric that fundamentally changes how GPUs connect to the network MetaRoCE, our open-source AI transport protocol. Launching [...] Read More... The post OCP Summit 2026: Powering AI with Open Innovations in Scale-Up, Scale-Out, and Scale-Across Networks appeared first on Engineering at Meta .
AbduzeedoMulti Author Blogsread at source
Web Design: Pensatori Irrazionali Digital Atelier
Pensatori Irrazionali built a technical web design portfolio combining brutalist typography, WebGL ribbons, and classical engravings. Pensatori Irrazionali structures its digital home as an interactiv...
Treehouse BlogMulti Author Blogsread at source
How to Get Free Coding Courses Through Your Public Library
You don’t need a paid subscription to start learning to code — if your local library partners with Treehouse, you already have access! Get Treehouse for Free Treehouse is available for free to patrons of participating public libraries across the... The post How to Get Free Coding Courses Through Your Public Library appeared first on Treehouse Blog .
Treehouse BlogMulti Author Blogsread at source
A Developer’s Honest Take on AI: An Interview with Gustavo Medori
iOS developer Gustavo Medori has shipped software for a decade. Here's how he uses AI to kill the busywork, write better code, and protect the parts of the job he loves. The post A Developer’s Honest Take on AI: An Interview with Gustavo Medori appeared first on Treehouse Blog .
SitePointThe Giantsread at source
Modern CSS Layouts: Building Responsive Websites Without Unnecessary Complexity
null Continue reading Modern CSS Layouts: Building Responsive Websites Without Unnecessary Complexity on SitePoint .
SitePointThe Giantsread at source
Writing Maintainable JavaScript: Practical Patterns for Scalable Web Applications
null Continue reading Writing Maintainable JavaScript: Practical Patterns for Scalable Web Applications on SitePoint .
AbduzeedoMulti Author Blogsread at source
TypeType Unveils TT Rationalist Typography
TypeType Foundry releases TT Rationalist version 1.100, refining slab serif typography with trapezoidal serifs and humanist proportions. Traditional slab serifs often suffer from Victorian clunkiness....
Jim Nielsen’s BlogMore Front-end Bloggersread at source
The Dock on Mac, From OS 10 to macOS 27
I wrote the chapter on app icon history for The iOS App Icon Book . The other day I found an old note stashed away where I had started researching the macOS version of that chapter (which Michael ultimately ended up writing). At the time, I didn’t know what to write. I mean, how do you write a history of icon design for the Mac? It’s rich! To get my creative juices flowing, I started by researching the different docks in macOS through the years and compiled them all into a single graphic (big shout out to this compilation of images on 512 Pixels ). I just wanted to preserve and archive that image. Check out the high-res version here . That’s it, that’s the post. Reply via: Email · Mastodon · Bluesky
SitePointThe Giantsread at source
Building Better Web Forms: Practical HTML, CSS, and JavaScript Techniques for Modern Websites
null Continue reading Building Better Web Forms: Practical HTML, CSS, and JavaScript Techniques for Modern Websites on SitePoint .
SitePointThe Giantsread at source
Introducing the Ampere System Profiler
A system-level profiling tool from Ampere that turns ambiguous performance symptoms - latency spikes, throughput drops - into system-level evidence before you tune the application or microarchitecture. Continue reading Introducing the Ampere System Profiler on SitePoint .
W3C BlogBrowsers, engines, etc.5 min read
We’re on a roll - EPUB 3.4 is coming
The Publishing Maintenance Working Group at W3C has been quietly working on yet another update for the EPUB3 standard, and we're excited to share what we have been up to. Our goal is to not only maintain the EPUB standard, but do our best to keep it in line with the needs of industry, and this update does exactly that. Your existing books do not need to change, if they conform to previous EPUB versions, they will conform to EPUB 3.4. Content you create today will automatically conform as well.
SitePointThe Giantsread at source
Reverse Engineering with AI: Trace Features Across Electron and Native Apps
Trace features through Electron IPC boundaries and native binaries using REA, an open-source MCP server and CLI for AI coding agents. Continue reading Reverse Engineering with AI: Trace Features Across Electron and Native Apps on SitePoint .
Engineering at MetaCompany/Startup Blogs8 min read
Shipping Media Over QUIC at Meta Scale for Instagram Live Ingest
Meta has begun deploying Media over QUIC (MoQ), an emerging open protocol for real-time video streaming at scale. MoQ will help simplify our protocol stack for live streaming video and enhance overall user experience for live video. We’re sharing how we shipped MoQ on Instagram Live ingest, and what the future looks like from here. [...] Read More... The post Shipping Media Over QUIC at Meta Scale for Instagram Live Ingest appeared first on Engineering at Meta .
Engineering at MetaCompany/Startup Blogs10 min read
Turning Opportunistic AI Inference Capacity Into Better Ads Recommendations
At Meta, we’ve built a system that enhances ads recommendations by leveraging idle inference capacity in our fleet. Two elasticity levers in the system allow ads recommendation work to expand across opportunistic capacity, without compromising baseline performance. This post describes how we designed and now operate the system at Meta’s scale and how it drives [...] Read More... The post Turning Opportunistic AI Inference Capacity Into Better Ads Recommendations appeared first on Engineering at Meta .
AbduzeedoMulti Author Blogsread at source
Inside the Craft of Skin First: Rebrand & Packaging by Uoi Studio
Uoi Studio rebuilt Italian skincare brand Skin First end to end: clinical white labels, pastel color-coded lines, precise spec-block typography. The tension here is between the clinic and the bathroom...
DigitalOcean BlogMulti Author Blogs5 min read
Introducing DigitalOcean Agent Data Services: The Data Foundation for Agents
Agents are only as capable as the context they can reach. An agent with reliable access to the right information makes decisions grounded in fact; one without it guesses. And the work agents produce is itself a critical asset: every execution trace, intermediate result, and…
AbduzeedoMulti Author Blogsread at source
Brand Identity: Plom by Brand Brothers
Brand Brothers designed the Plom brand identity, translating athletic recovery and botanical energy into bold typography and modular geometry. Founded by Toulouse venture V21, Plom is a functional rec...
DigitalOcean BlogMulti Author Blogs4 min read
Introducing DigitalOcean Insights: Built-in Observability for Your Agents, Applications, and Infrastructure
Coding agents have changed how fast teams ship, and more of the software they ship now includes agents. A production agent spans model calls, routing decisions, tools, and the infrastructure underneath. When an agent run slows down or fails, the cause could be anywhere in that…
DigitalOcean BlogMulti Author Blogs6 min read
Introducing DigitalOcean Signals and Simulations: see how your agents and models really behave in production, then test the fix before it ships
You ship an agent. It mostly works. Then the feedback loop becomes a support ticket: a user got the wrong answer, a tool call looped four times, a refund went out that shouldn’t have. Standard observability tells you the system was up and the latency was fine. It can’t tell you…
Frontend Masters BlogMore Front-end Bloggers11 min read
Tips and Tricks for Using TanStack Start with Cloudflare Durable Objects
Some hot tips on using middleware for simplifying Durable Object creation and managing WebSocket connections.
SyntaxPodcastsAudioListen
1046: The Pi Updates are insane
Scott, Wes, and CJ break down the latest Pi updates, including durable long-running agents, Codemode, and MCP support, then debate whether pull requests are dead in favor of issues. Plus Supabase picks up Turso, Screen Studio 4 drops, JavaScript Composites bring value-based…
Bruce Lawson's personal siteMore Front-end Bloggers2 min read
EU, EU, It’s off to work we go
Last week, I had an exciting few days in Brussels, meeting with the European Commission with other browser vendors, technology groups, and representatives of a Big Tech Gatekeeper about the latter’s sustained and relentless malicious compliance with the Digital Markets Act, the EU’s law “to make the markets in the digital sector fairer and more […]
Flavio CopesMore Front-end Bloggersread at source
How I fixed a full Ubuntu server disk with Codex
My Sendy server stopped responding with the disk at 99%. The database was 528 MB, but MySQL binary logs had grown to 41 GB. Here is how Codex walked me through finding them, purging them safely, and setting an expiry so it never happens again.
SitePointThe Giantsread at source
Designing a Safer Account Recovery Backend for Consumer Apps
null Continue reading Designing a Safer Account Recovery Backend for Consumer Apps on SitePoint .
SitePointThe Giantsread at source
Beyond the Password Reset: Building Recovery Experiences That Protect Online Shoppers
null Continue reading Beyond the Password Reset: Building Recovery Experiences That Protect Online Shoppers on SitePoint .
HeyDesignerDeveloper/Designer Newsread at source
The convergence of design
mkdir: Curated design inspiration directories, Anatomy, On giving fluid interfaces an anchor.
AdactioTop Front-end Bloggersread at source
Back at the Vehicle Assembly Building …twenty years after I got to go inside it: https://adactio.com/journal/1208
remy sharp's b:logTop Front-end Bloggers4 min read
My AI policy [blog]
There's no shortage of commentary on LLM usage and I've penned several posts that have never left draft status because in part I can't articulate exactly what I want, and partly because there's so much noise around the subject. That's been true for the last few years but as an senior (and old) developer I think it might be useful to at least put in writing what happens to be true for me this moment in October 2026. Fair notice: this post will only briefly cover any policy I personally hold and quickly move into my opinions about LLMs and our community. On this blog Yeah, no. My words are mine. They might be regurgitated in your LLM chat session, but every typo, grammar failure and angry word is mine here. Additionally, the code that drives this site is almost all mine. I do use a few node libraries here and there (probably pug is the biggest one), but the "author code" is all me too. To be clear, this isn't because I'm some kind of shining light in the dark, it's because I need to protect some space for me to continue to practice development. I personally understand why an LLM would be used for code, but I can't fathom why someone might use it for their words. But that's for me, not for you to worry about. I can see legitimate LLM use for ideation, legibility checking and translation - but that's not for me and not for this blog. Elsewhere I'm not entirely anti-AI. My position has changed over time, probably linked to progress in progress in generative/better auto complete in code. But I'm not pro-AI either. I've not one sung it's praises to anyone. I might tell you about a thing I've used an LLM to make, and I do appreciate even writing about the experience might be read as pro-AI, but you won't find me telling you that you should use it. I'm using an LLM to complement my client work. My work is a mix of understanding a full system, directing the agent (which might be slightly different if I didn't work in a silo) and critically reviewing code changes. I've always considered my job (for over 2 decades) to be a communication task. To communicate business needs to functional code. That's to say, the actual implementation details don't concern me too much. In the same way a junior developer would code the solution in a different, and likely much more verbose way to me, but if it solves the business needs, and works, then it's not my job to rewrite their code. Likewise, if the task is to transform some data, it really doesn't matter what language the solution is, so long as it works (obviously you can get into the question of maintenance, but each case is unique). My point: it's not a hill I care to die on. On that note, I genuinely think we, the web community, need to back off shaming other developers for their choices. Regardless of whether it's using an LLM or using React, or Tailwind, or jQuery. It's an ugliness that doesn't sit well whilst trying to create an open and progressive community. I'm certainly guilty of this and I'm trying to get better. There's so many people that aren't the hard core tech bros pushing an agenda, and whom just want to make things. I recently heard of a new developer who wanted to share their web site with their peers in a "show off your work" channel. The channel was intended to be supportive, but because they had used React and hosted on Vercel, they held it back for fear of shaming. They weren't there banging a drum about how others should use these options, but just that they were chuffed to have made a thing, and yet we'd made them feel that they couldn't. The reason I've never managed to publish those earlier mentioned drafts is for fear of ostracising myself from my peers. I'm sure I'll be fine (I'm a big boy after all), but it's just a weirdness that we've made for ourselves. My ethical position on AI companies By "AI" companies I'm referring to OpenAI, Anthropic, Twitter (or Grok, or whatever the hell it's supposed to be), Microsoft, Google and probably Amazon. The companies that a driving data centre development across the globe. In short, it's fucked. The greed is grotesque and the ruin they're laying to waste is heartbreaking. In reading Empire of AI I came to understand the real impact on the communities the data centres really have. I struggle to reconcile the term "theft" with the mass training on public content, but it's semantics that I'm struggling on. The reality is that we, the people whose words make up the web, were taken on an unprecedented scale, and zero credit was given - let alone consent (though our content was always designed to be ingested in different ways - RSS aggregators being one such example). Then this content was used to create unimaginable sums of money for the super rich and none of this was returned to the authors, again, not even a thank you. I really do detest these companies (at different levels, at different times of the month), but I wonder if it's because I've got more of an understanding, because by comparison, I don't actively detest airline companies or oil companies for that matter. Those are "background bad". This does live within me as a constant tension with my current LLM usage. So that's it. More of a brain dump mixed with some of my feelings on our community. I've no doubt this will change, and possibly within the next 12 months given how quickly the state of the world is changing.
AbduzeedoMulti Author Blogsread at source
How cheeeeese Reimagined Brand Identity for TGLF
cheeeeese turns the Geneva Learning Foundation's initials into a brand identity: one labyrinth on a pixel grid, with a key in a single stroke. The Geneva Learning Foundation is ten years old, and its ...
Jim Nielsen’s BlogMore Front-end Bloggersread at source
The Fascinating World of Domains
Pete Millspaugh has a lovely article over on WIRED that peers into the world of domains. (If you’re as interested in the esoteric details of domains as I am, follow Pete’s writing at Dot Com Press .) You should just read the article, but here are a few things that stood out to me. The .com Registry Did you know who the registry for .com is? I didn’t. The registry that owns .com, Verisign, makes a billion and a half dollars every year just by keeping the lights on. To Verisign’s credit, the lights never go out: It reports 100 percent uptime over the past 28 years. It’s a pretty slick business model, watching over a database of words and collecting annual renewal fees. Warren Buffett thought so too, investing in Verisign in 2012, when its stock price was about one-eighth what it is today. Why is it simultaneously surprising and not surprising that the company running .com makes billions and has 100% uptime over almost three decades? Maybe GitHub should reach out for some advice, lol. Buying Domains Is a Spy Thriller Apparently the last time you could buy generic top-level domains (gTLDs) was in 2012. So now that ICANN is providing another window of purchases in 2026 — and nobody knows when another window will open — there’s a lot of interest in capitalizing on these moments for new gTLDs. most organizations [are] extremely secretive about their plans. One applicant from the last round tells me companies were flying around the world, meeting in person to avoid any risk of digital leaks, avoiding Gmail for fear of Google spying. Instead of email or video calls, she flew to London, then to Madrid. “We did it all in person. People got a little weird and scary, super paranoid.” There’s a certain irony to this — people flying around the world to conduct business on owning a piece of the internet because they don’t trust the internet. It appears the future of the internet is to be negotiated offline lol. More Domains = More Online Handles We haven’t had new gTLDs since 2012. Why do we need more? I can imagine a future where expressive top-level domains become our personal brands, identities on the internet. This is already true in some nerdy corners of the web, like on Bluesky, where your domain is your username. I don’t call my internet friends Neal and Luke, I call them neal.fun and luke.zip. Instead of joining the land rush to grab our username on each new social media site, we’ll carry our domain around the web with us. I’m telling you, domains are the OG handles on the internet . More domains mean more opportunities for individual expression at the root layer of internet infrastructure — that makes sense for a web that’s meant to be worldwide! You Think You Have a Domain Vice? As developers, we often joke about our addiction to buying domain names for our side projects. But buying a domain name — e.g. my-side-project.com — is child’s play compared to buying a generic top-level domain name (gTLD). That’s where the domain whales are. ICANN charges a $227,000 application fee for each string, to recover the cost of running the program. The $36 million or so that Nova will need to cover those fees […] is coming from the personal bank account of Yoni Belousov, a reclusive domain investor (industry jargon: “domainer”) who’s been in the business since he was 14 years old. Next time somebody asks me what I’d do with an insane amount of wealth, I now have the jargon for an answer: “I’d become a domainer.” A Few Fun Facts to Close A few things about domains I didn’t know until I read this: all two-letter extensions are off the table. Those belong to countries, like .co in Colombia and .me in Montenegro and .ai in Anguilla. If you want to run a geographic TLD, like .nyc or .paris, you need approval from that municipality your string can’t be too similar to an existing one (.corn is a no-go; looks too much like .com) certain special strings are off limits, like .icann and .www (wouldn’t that be a trip). www.www would be a baller domain! Just think of the recursion you could do with that on the subdomain level. Reply via: Email · Mastodon · Bluesky
SitePointThe Giantsread at source
Designing Reliable Offline Experiences for Modern Web Applications
null Continue reading Designing Reliable Offline Experiences for Modern Web Applications on SitePoint .
Stéphanie WalterMore Front-end Bloggersread at source
Pixels of the Week – October 11, 2026
This week brings some resources on neurodiversity and cognitive accessibility, explains why design struggles to justify its value to business, and how AI exposes design’s craft crisis. Also don't miss some nice accessible color combinations and funny wildlife photos.
AbduzeedoMulti Author Blogsread at source
Branding: Culture House Sunderland by Studio Blackburn
Studio Blackburn designed the identity for Culture House Sunderland around a rotating C&H monogram that clicks into a house silhouette. The strongest move is the container itself. A heavy black ho...
David BushellMore Front-end Bloggers4 min read
D-Bus Hell
The time has come to address the elephant in the comments. Whenever my blog hits a place with a comments section the most predictable comment I see — besides some variation of “this idiot is utterly delusional!”† — is this one: “lol I read the domain as “D-Bus Hell” Random commenter”I’d prefer if […]
Adam ArgyleTop Front-end Bloggersread at source
WWW Ep255 Meta Harnesses Medical Midjourney And Specialists
Ep #255 Meta-Harnesses, Medical Midjourney, and Why Specialists Are Cooked Robbie and I are back together, talking token limits, OpenCode burning budgets, work trees for parallel agents, Impeccable's art direction grilling, CodeRabbit versus Copilot for PR reviews, self-heal…
Ethan MarcotteTop Front-end Bloggers2 min read
All watched over by algorithms of loving grace.
If you liked that, have you considered you might enjoy: more of that
Lea Verou’s blogTop Front-end Bloggers27 min read
The best way to use icons in Web UIs
TL;DR? Jump to demo I’ve always had a soft spot for icons 1 . Not only do they add polish to a UI, they can also tangibly improve usability. Familiar icons help users find what they need quickly, since we recognize pictures much faster than we read words. And as a web architect…
Sara SoueidanTop Front-end Bloggers3 min read
My top picks for Interop 2027
I love the Web platform, and it’s a privilege that we, the web community, get a chance to influence what browser makers work on every year. For the second year in a row, Firefox has created a page that allows us to rank the Interop 2027 features that we care about the most.…